 Backed by Atlantic VC



Future optimisation tracking
See how far cost per task can still fall — tied to your own financial plan.
 cta




The same models at the same quality —we simply sell them 35% cheaper.
Floctaputs the models everyone else runs on one EU platform, at exactly the same quality. Routing, prompt compression and caching underneath are what let us sell them to you 35% below the market price.
Seat plan or API key — either way you choose: 35% cheaper tokens, or 35% more usage for the same money.
One web app for open-weight models, company knowledge, files, images and voice — ready to use without API keys or AI expertise.
Work with all of the world's best models in one interface — from frontier to open-weight, with GDPR-compliant deployment options.
Open-weight models
Frontier models


Search and work with internal data from over 50 integrations.
 (opens in a new tab)
The Wispr Flow model learns how you speak, rewrites sentences as you talk, adapts to your tone and style, and improves its predictive completions over time.
Send the Q1 pipeline follow-up in my concise style, include the updated numbers, and complete the final sentence naturally…



Drop in documents, spreadsheets, meeting recordings — from Drive, Slack, Meet or anywhere else.


Drop files to attach
Selected open-weight models are tailored using explicitly approved company data, terminology, conversations and task examples. The result: models built for your workflows, with better task-specific quality, faster execution and lower long-term costs.
Approved company data
 GDPR-ready · quality gate passed
Vlincta identifies the best open-weight models for your workloads and deploys them privately in your cloud environment—with only a few clicks and without your team building the infrastructure.
Best-fit open-weight modelsSelected for your workloadsPrivate cloud environmentReady through one managed flowSee how far cost per task can still fall — tied to your own financial plan.
Point your own provider key at Vlincta and keep every tool you already work in.
Live dashboards for token prices, cost per task and the full trace of every run.
Always on: the token price forming right now, across every request.
Two things you can check rather than take on trust: where your data actually runs, and who put money behind this before anyone had to.
GDPR compliant by design
Your prompts, your files and your company context stay on EU infrastructure, under EU law. No transfer to a third country is needed for Vlincta to do its work.
 GDPR
 SOC 2 · soon
 PCI DSS · soon
 HIPAA · soon
Hosted in France
Certifications held by Scaleway, our hosting provider.
Built in Berlin
GDPR applies today. SOC 2, PCI DSS and HIPAA are in preparation — we publish each one when it has been independently audited, not before.
Pre-seed closed in two weeks
Atlantic did not take a flyer on us. Two weeks after Christophe first heard the idea, the pre-seed round was closed — no process, no second meeting to think it over.
The round
The investor
Portfolio companies you already know:
The same fund behind SoundCloud, GetYourGuide, Omio and Choco. Those are their portfolio, not our customer list. A VC that understands who has potential and helps them get there — just like us :)
We cannot make every backend system public — they would be copied. These are four that work particularly well.
Cost-efficiency platform
Four systems
01 — TETFU Routing
Most requests cannot be got wrong. Vlincta finds those and routes them to the cheapest open model that clears the bar.
The models it routes across
02 — Semantic compression
Long context is compressed and cached, so a repeat call carries a reference, not the history.
Context it compresses
03 — Latency optimisation
A call that stalls gets retried — and a retry is one answer, billed twice.
Where the call actually runs


04 — Tailored open weights
Open-weight models tuned on your work, running in your own cloud.
The same weights, tuned on your data

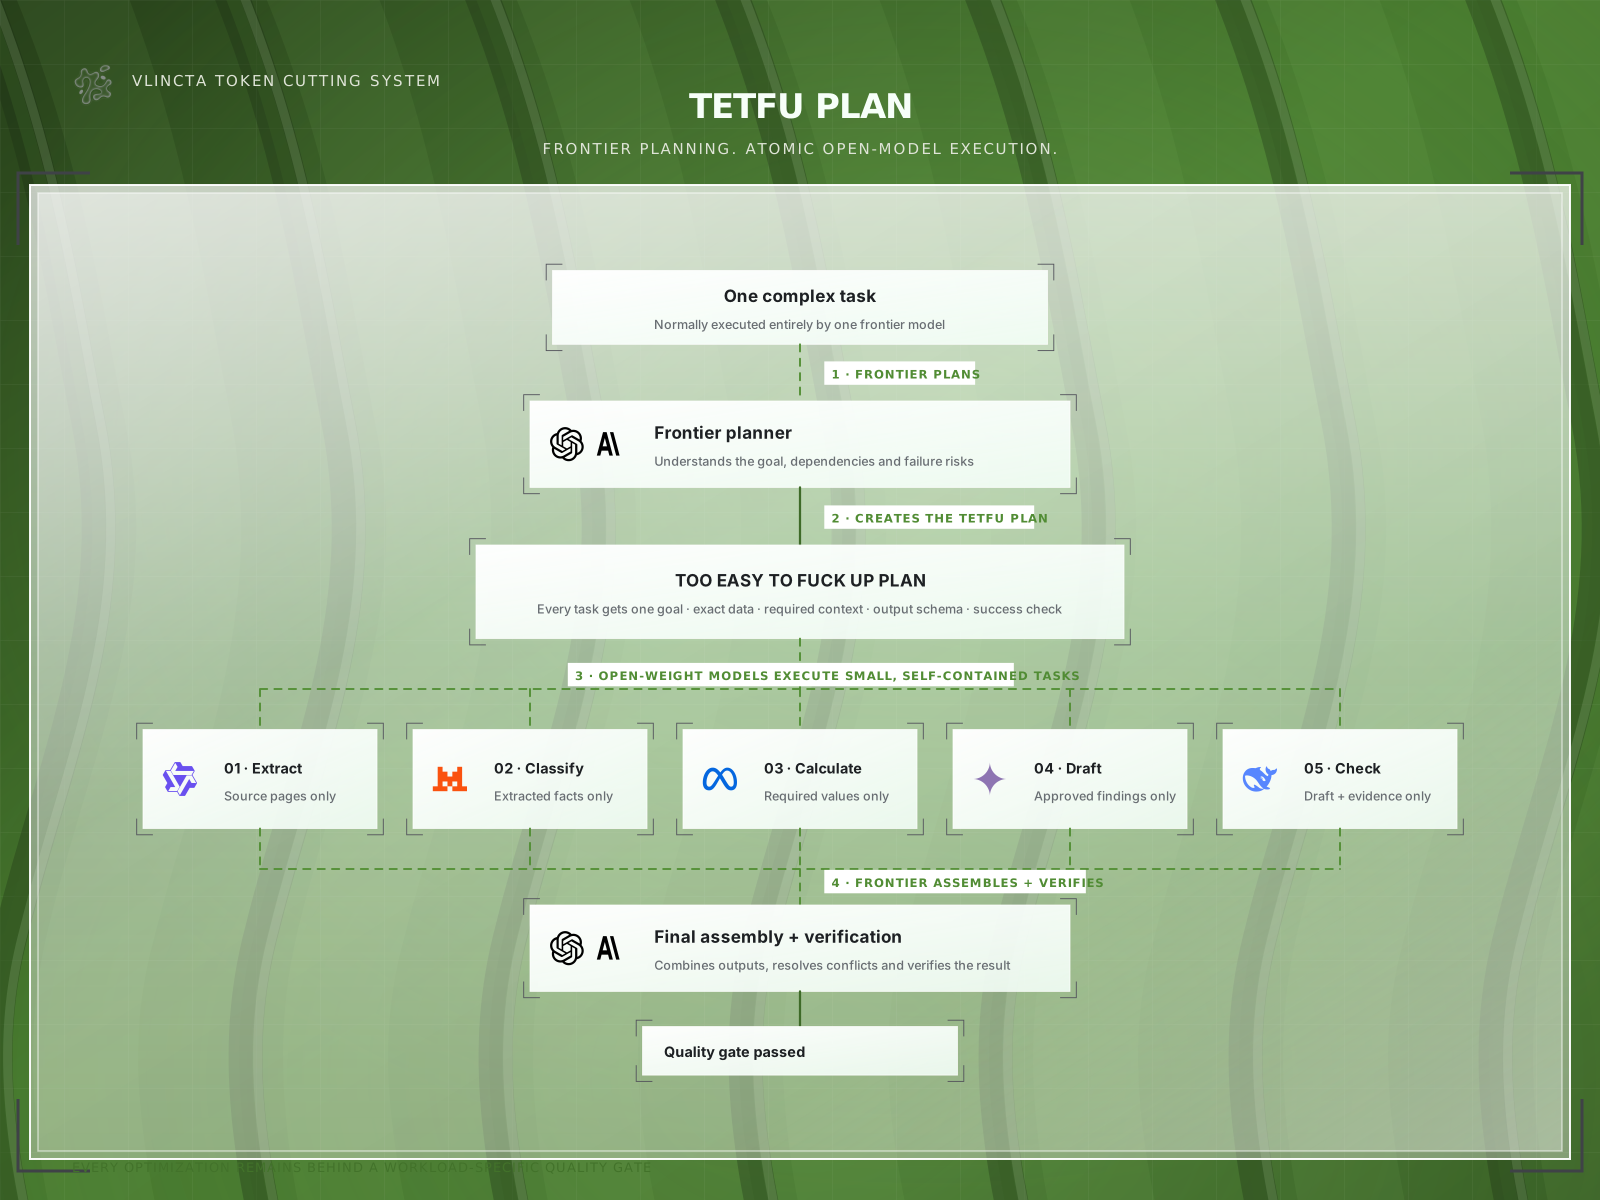
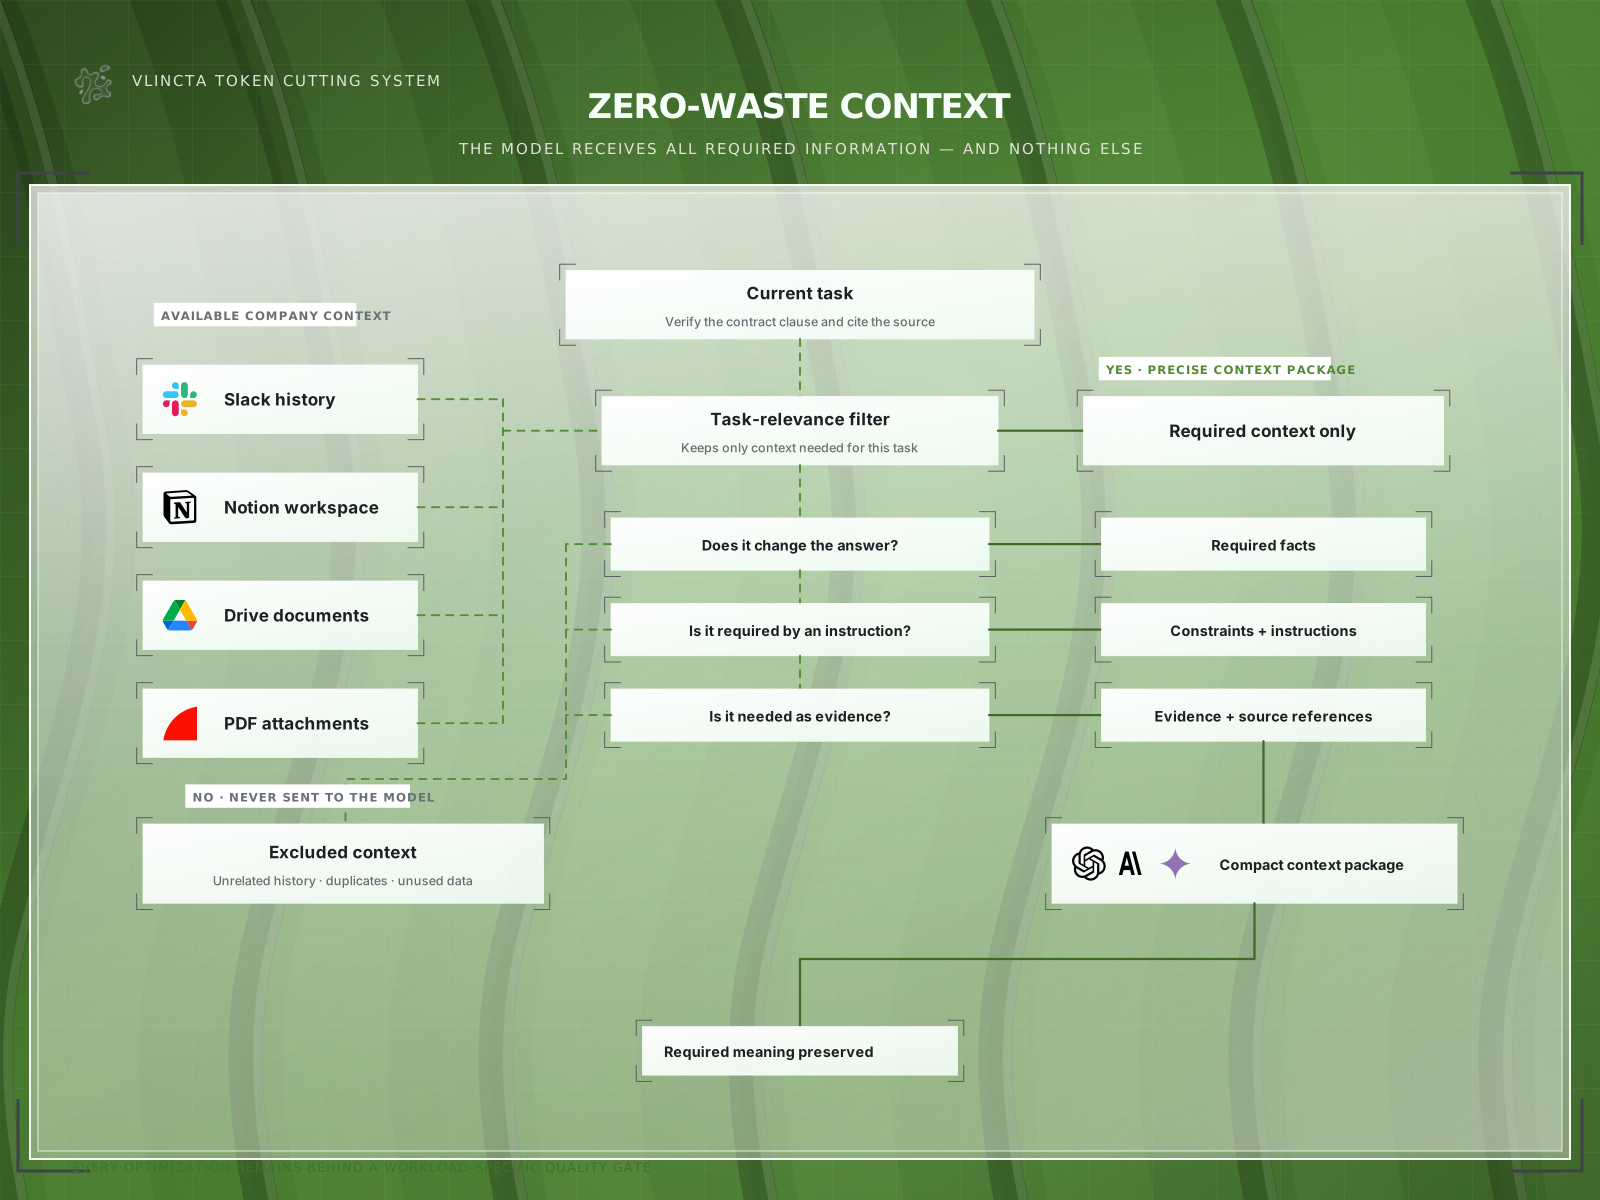
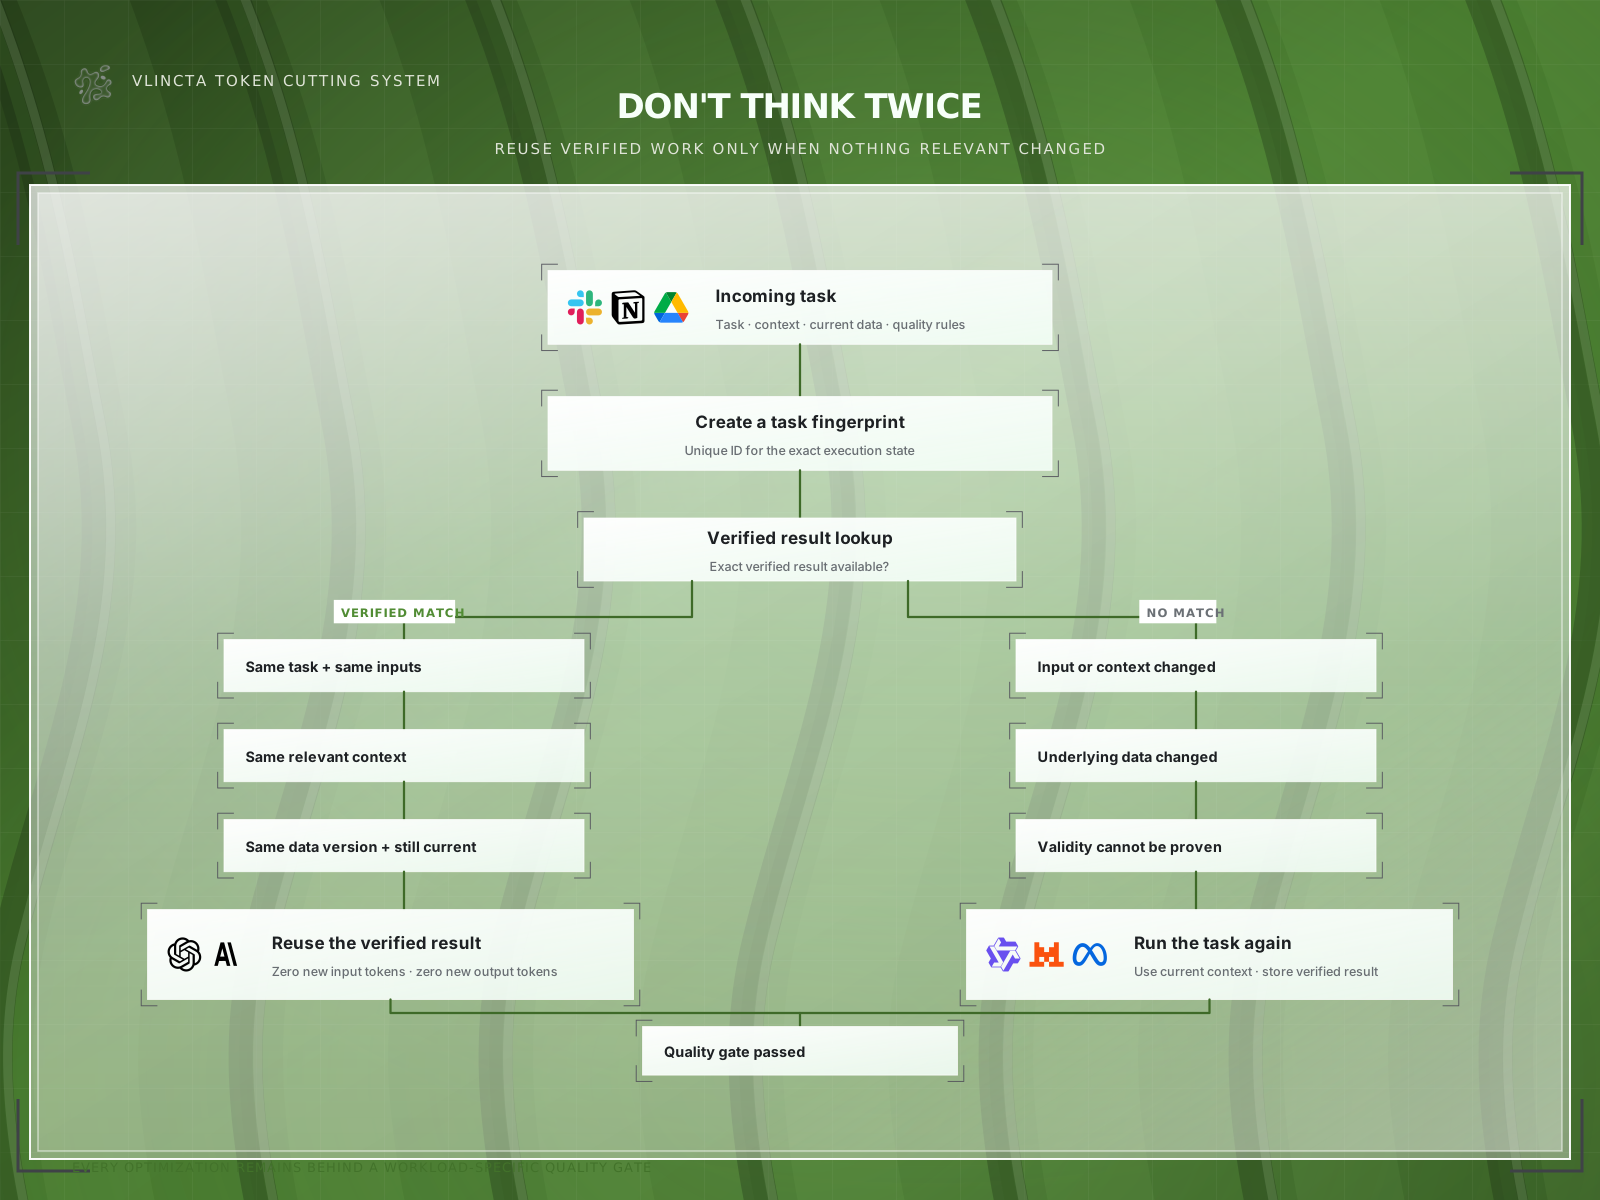
How Vlincta reduces tokens while holding the same quality — and, over time, improves quality for high-value use cases. The longer the system runs, the more efficient it becomes. These are only three of the many systems built into the Vlincta layer.
01
A frontier planner breaks one complex request into atomic, verifiable subtasks. Each step receives one goal, the exact data it needs, a defined output schema and its own quality check before final assembly.
02
Vlincta filters company context against the current task and sends only required facts, constraints, instructions and evidence. The model receives less noise while the meaning needed for a high-quality answer stays intact.
03
Every task gets a fingerprint. When the task, inputs, relevant context and data version still match, Vlincta reuses the verified result instead of spending tokens twice. Any meaningful change triggers a fresh run.
Your prompts and your workflow train a model that serves just you, in your workflow — if your workspace opts in. Not a shared model that learns from everyone. Not on by default.
Nothing you send trains anything by default. A workspace turns this on itself, in its settings, the same way it opts into content retention today. Until then your prompts are routed, answered and metered — and that is all.
The prompts and the workflow of one workspace shape a model that serves that workspace and no other. There is no shared model that learns from everyone; isolation is per workspace, like every table in the system.
Personal data is filtered out before anything is learned. The result is validated through the same evaluation loop that decides which open-weight models are enabled at all, and it enters your registry as a row with a price and a snapshot date — a model call like any other, on a ledger row.
This is the last phase of the Flocta plan, and it follows from the first: metadata only by default, content only where a workspace has chosen it. EU-region processing by named subprocessors, here as everywhere.
From engineering with GLM 5.2to marketing with Qwen3.5 397B
GLM 5.2Open-weight Q1 Pipeline.xls
Get a focused estimate in two quick questions.
Question 1 of 2
Include paid Claude, ChatGPT, Langdock or comparable seats.
Tell us what you want to accomplish with Flocta. Sign in to send your first request — every answer runs inside your workspace.
No model request is sent from this page. Submitting signs you in; nothing typed here leaves the browser. Privacy
Everything you might want to know about your data, the models, the price and how Flocta fits next to what you already run.
Flocta is an all in one AI platform for small and medium businesses that reduces large language model token costs by 30 to 50 percent, depending on the workload. The saving is engineered, not taken out of the answer. Three systems do the work: semantic caching reuses results the platform has already produced for an equivalent task; context compression sends a model only the facts, constraints and evidence the task needs instead of the whole history; and routing gives each request to the cheapest model that can still hold the quality the task requires. It works the same whether a team brings seat plans or its own API keys: the same models at the same output quality for roughly 35 percent less, and up to 20 percent better on narrow, repetitive work where a specialised model beats a general one. Chat, company knowledge, files, voice and workflows sit in one interface, and every request is processed on EU infrastructure under GDPR.